A World Model Can Lower MSE and Still Choose the Wrong Action
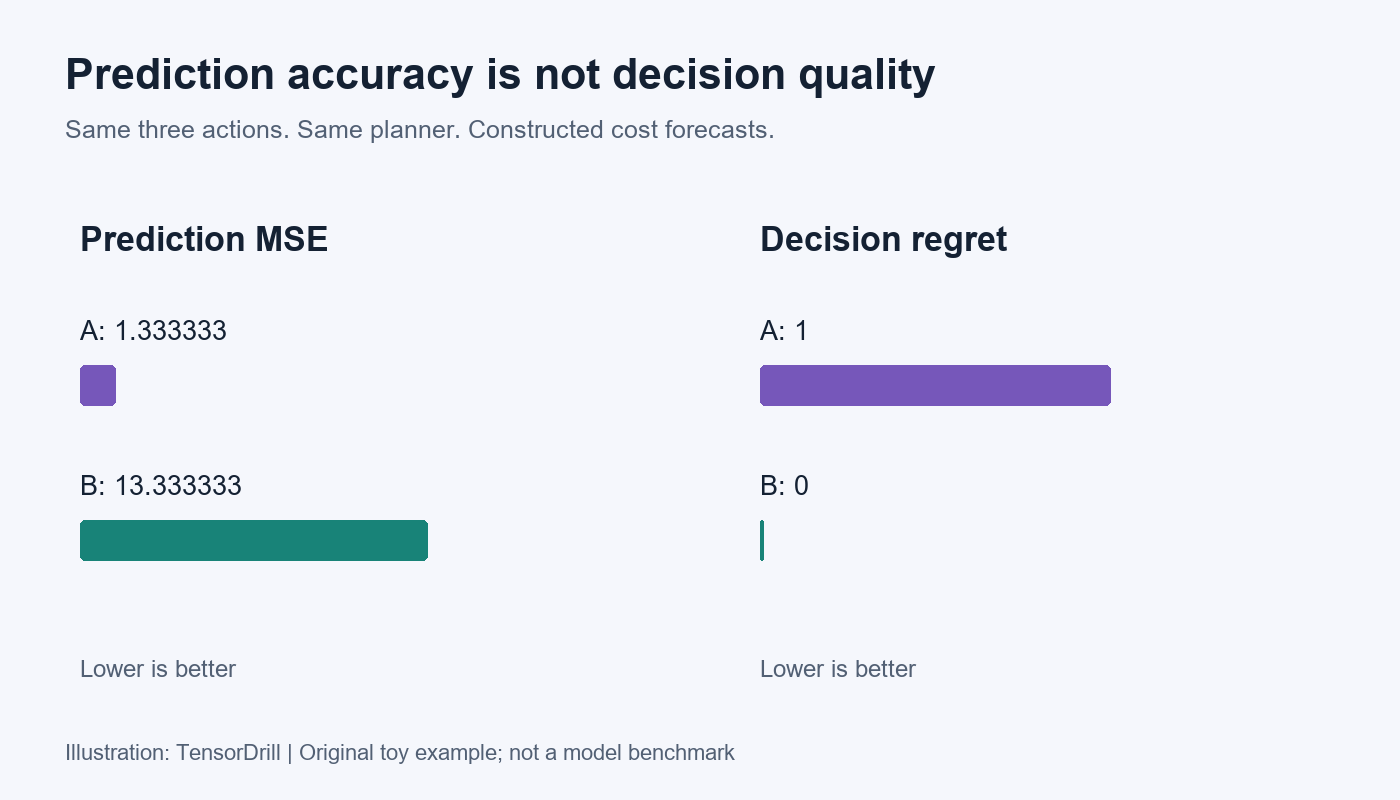
Suppose two world models feed the same planner. One has ten times less mean squared prediction error. Would you deploy that one? Before answering, inspect which action each model chooses. This post us
Responses
Markdown supported · ⌘↵ to post
Kartik N V J K
AI Developer | Making AI reliable, trustworthy & accessible to everyone | Active community contributor
I'm taking the gap > 2 * epsilon condition back to my own evals, since it gives a concrete check in place of average error. I've seen the same pattern with LLM judges scored on overall agreement, where a judge matches humans on most items and still flips the close calls that decide which prompt ships. Your two-action example, where the (10, 11) offset keeps the ranking and (0.6, 0.4) flips it, is the one I'd show anyone reading MSE as a ranking metric.