Narrowing this to whether the right page still lands in the top 5 is the right scope, and it is the measurement most cross-lingual discussions skip past on the way to answer quality.
The thing I would watch in the numbers is that degradation tends to be uneven rather than uniform. Domain terms that are loanwords survive the language switch nearly intact, while everyday phrasing collapses, so a golden set weighted toward jargon looks far healthier than real user questions do.
If you extend the series, translating the query into the corpus language before retrieval is usually cheaper than a multilingual embedder, and it has the advantage of being inspectable when it goes wrong.
Yup, I have now measured it inside one language. I rewrote the 20 English golden questions in a customer's words. "Bank" for PSP, "instant transfer" for SCT Inst, none of the section's own terms. The original wording puts the answer page in the top 5 for 17 of 21 questions, when the everyday wording does it for 14.
One example: "available on weekends and public holidays" finds the page at rank 2 vs. "Can I send an instant transfer on a Sunday?" finds it at rank 46.
The page says "Calendar Days". So a golden set in the rulebook's own words does look healthier than real questions. Here the gap is 3 of 21, before any language change.
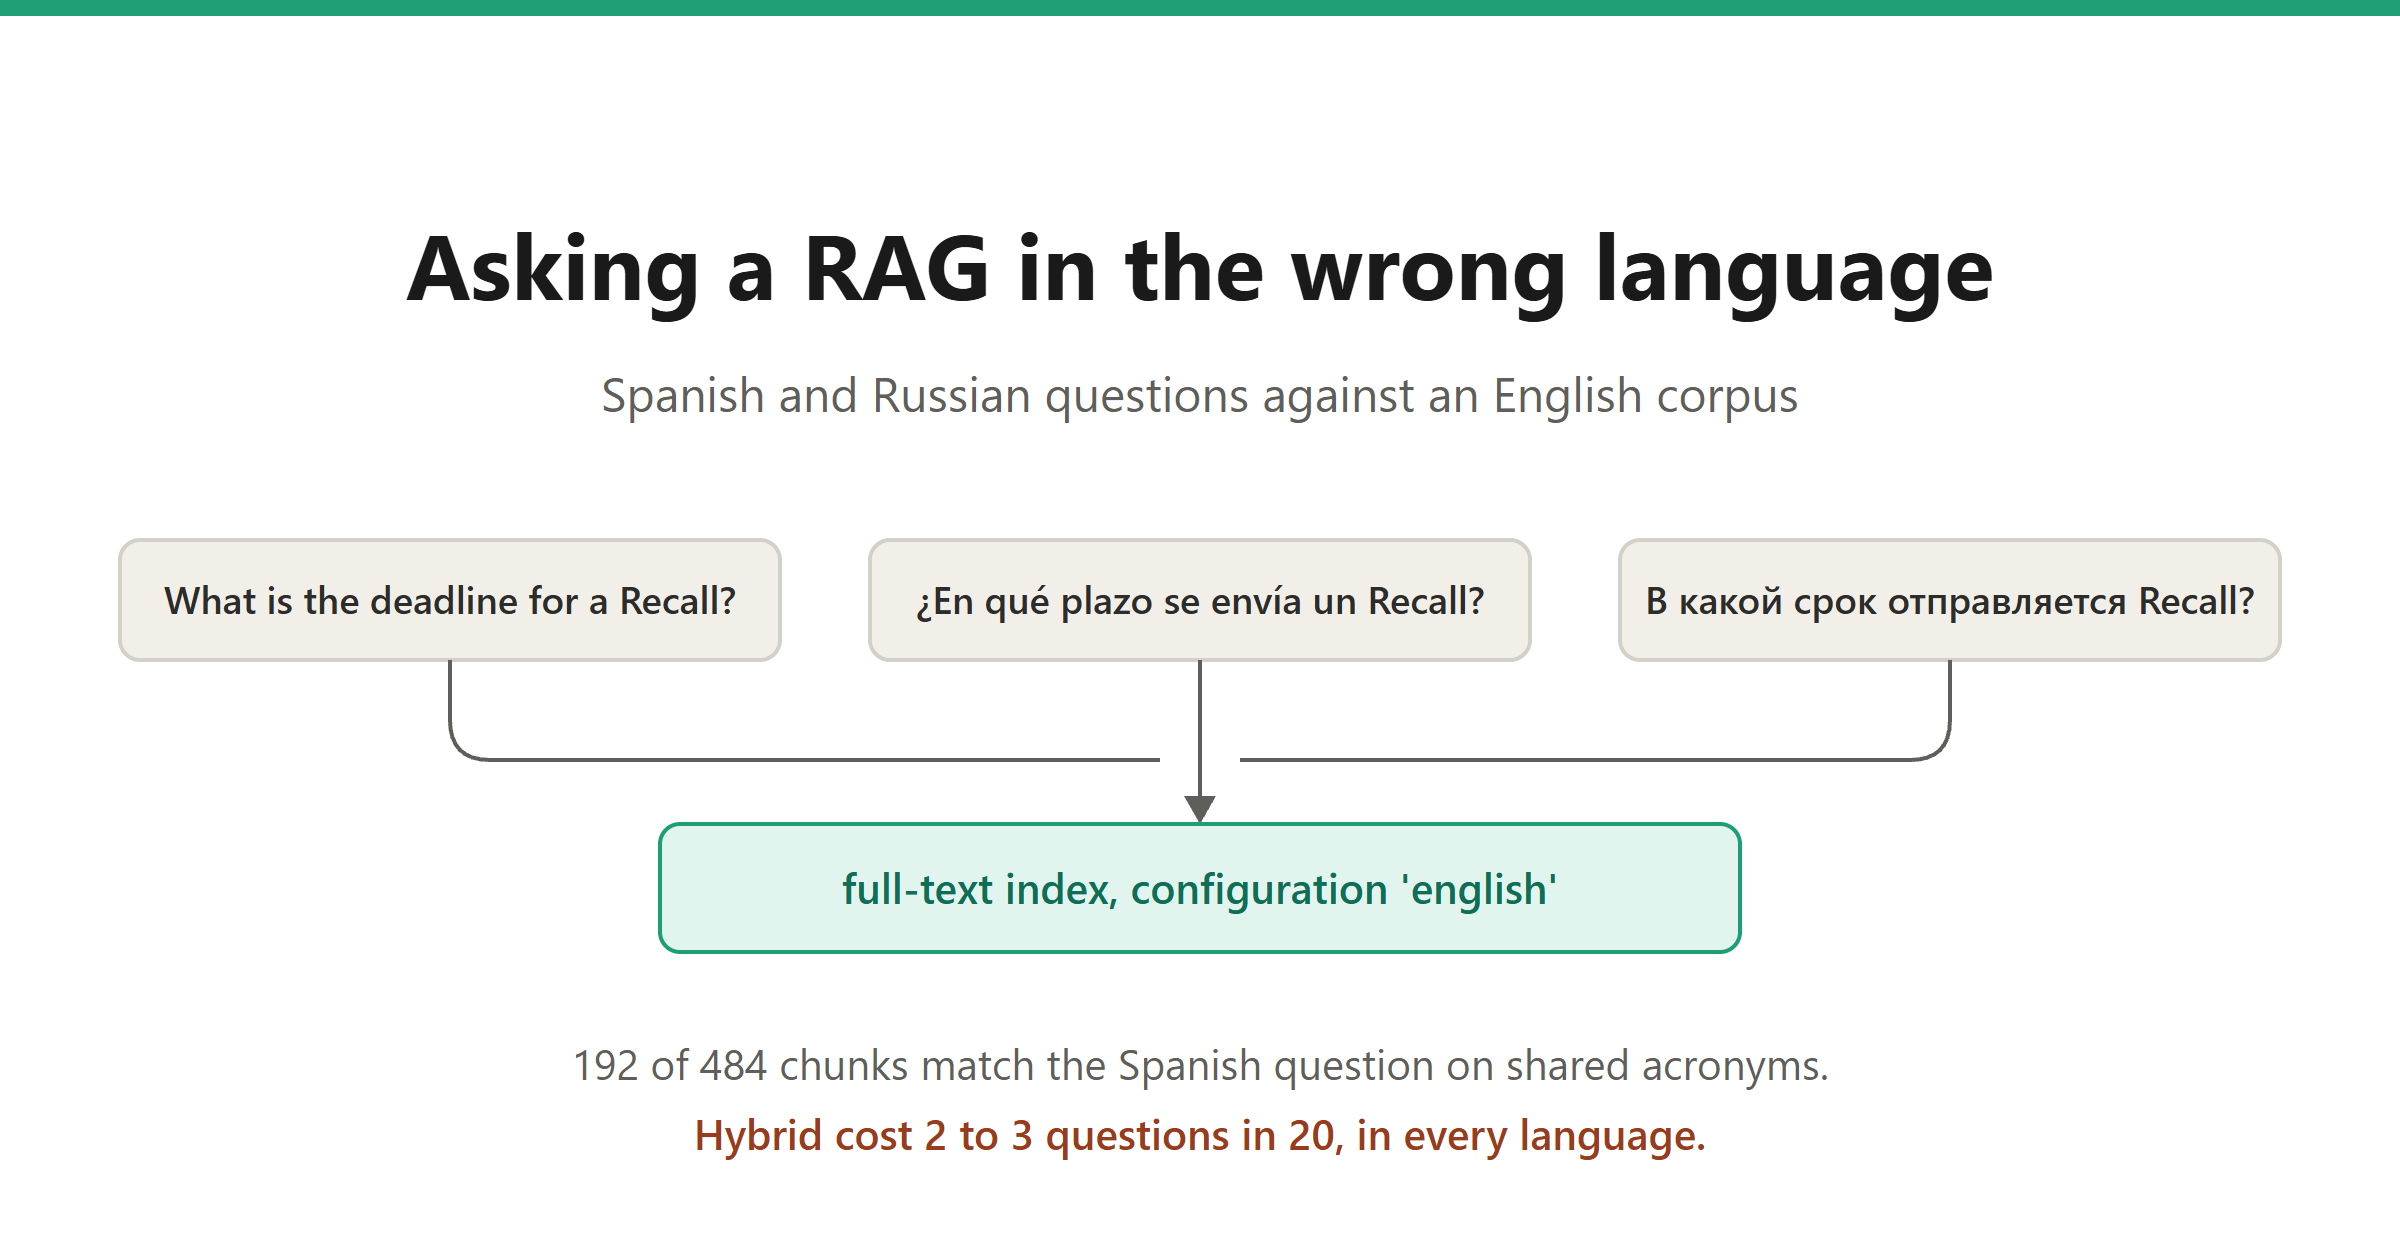
On translating the query first: I measured it in this article. It brought Russian to within one question of English and did nothing for Spanish. Two questions already sat at rank 4 and 5 in English, so any rewording pushes them out. Inspectable, agreed. It is also a paraphrase, and the fragile questions pay for it. The phrasing numbers go out as the next piece.
That is a fair correction: you had already tested query translation, and I overlooked that result. Russian improving while Spanish stays unchanged makes translation a conditional intervention rather than a default fix.
The 17/21 versus 14/21 comparison also isolates wording before language enters. I would keep the original and everyday versions paired by question ID and inspect which failures overlap with the translated variants. That would separate a language-sensitive miss from a question that is already unstable under paraphrase.
Ahmet Özel
AI Engineer. Computer Vision, RAG and LLM agents.
Narrowing this to whether the right page still lands in the top 5 is the right scope, and it is the measurement most cross-lingual discussions skip past on the way to answer quality.
The thing I would watch in the numbers is that degradation tends to be uneven rather than uniform. Domain terms that are loanwords survive the language switch nearly intact, while everyday phrasing collapses, so a golden set weighted toward jargon looks far healthier than real user questions do.
If you extend the series, translating the query into the corpus language before retrieval is usually cheaper than a multilingual embedder, and it has the advantage of being inspectable when it goes wrong.