Async AI Pipelines in FastAPI: Streaming, Queuing, and Long-Running Requests
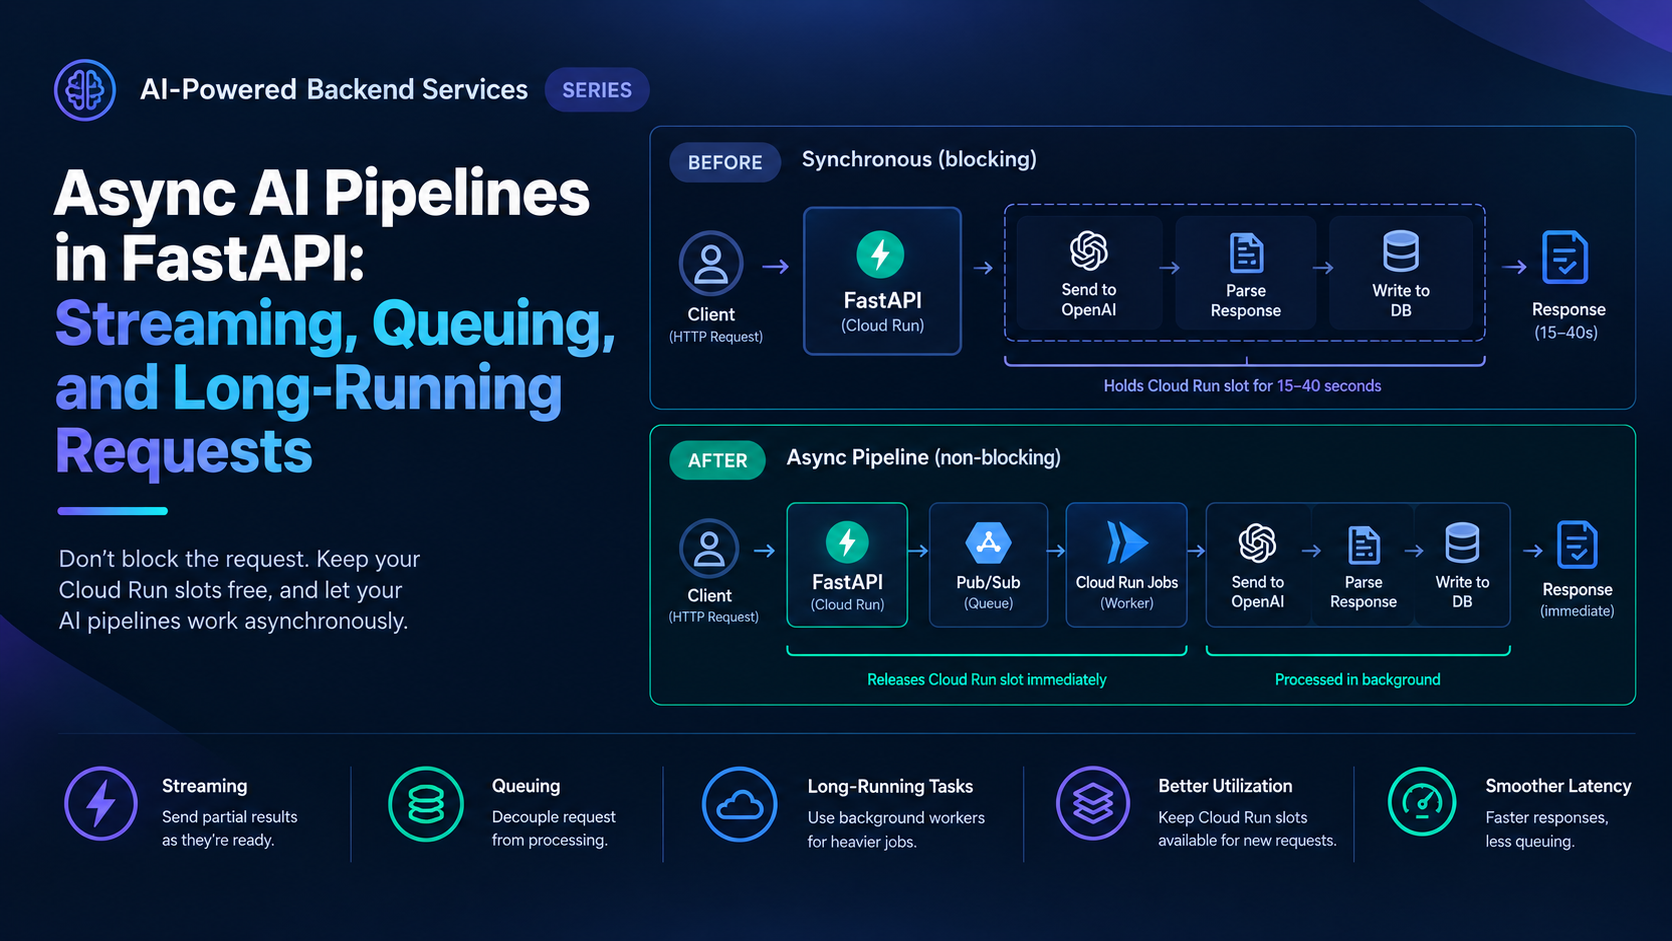
The document extraction endpoint was synchronous. A request came in, the service sent the document to OpenAI, waited for the full response, parsed it, wrote to the database, and returned. Each request
Responses
Markdown supported · ⌘↵ to post
No responses yet.