HHassan Aziz1m ago · 14 min readHow semantic search works, with a Python exampleThe short version Semantic search ranks results by meaning: the query and every document become vectors, and the documents whose vectors point closest to the query's come first. An embedding model tuhassanrants.hashnode.dev
ZZyVOP7h ago · 11 min readChoosing a Vector Database: pgvector vs Dedicated StoresThe real question isn't which vector database is best. It's where your vectors should live: next to the rest of your data in Postgres, or in a system built only for similarity search. Many teams alreablog.zyvop.com
RRounak Show22h ago · 8 min readUnderstanding LLM Embeddings from Scratch — Part 5: Word2VecIn Module 4, we treated embeddings as raw parameters—numbers in a matrix tuned by backpropagation to minimize a loss value. Now, we step back from the raw mechanics to look at the emergence of meaningrounakshow.hashnode.dev
RRounak Show1d ago · 10 min readUnderstanding LLM Embeddings from Scratch — Part 4: How Does an Embedding Actually Learn?So far, we've learned why embeddings exist, how vectors, dimensions, and similarity work, how nn.Embedding stores vectors and retrieves them using token IDs, how padding and attention masks handle var1Arounakshow.hashnode.dev
RRounak Show2d ago · 10 min readUnderstanding LLM Embeddings from Scratch — Part 3: The Embedding MatrixIn Module 1, we learned why embeddings exist. In Module 2, we understood what vectors are, including their dimensions, magnitude, dot products, and cosine similarity. Now, let's connect everything to 1Arounakshow.hashnode.dev
RRounak Show3d ago · 7 min readUnderstanding LLM Embeddings from Scratch — Part 2: Vectors, Dimensions, Dot Products & Cosine SimilarityIn Module 1, we learned that an embedding layer converts a token ID into a vector. For example: cat = [0.90, 0.10] dog = [0.85, 0.15] We said these two vectors look similar, but we haven't explained w1rounakshow.hashnode.dev
RRuncrate5d ago · 6 min readEmbed your docs on a rented GPU or call an embeddings API? We measured both with bge-m3Written by the Runcrate team, using our own API. Every RAG project hits the same fork: self-host the embedding model on a GPU, or pay an embeddings API per token. The usual arguments are about privacyruncrate.hashnode.dev
Ttarini sunil6d ago · 3 min readI Built a Knowledge Radar. Now It's Your Turn.The final experiment in the Hidden Signals series. What If Documents Could Tell Us More Than What They Say? Over the last few posts, we've discovered something interesting. Documents have hidden patteai-content-utilties.hashnode.dev
ZZyVOPOct 20 · 13 min readHow RAG Works, End to End: From Raw Documents to Grounded AnswersA language model knows a great deal, and none of it is about your company’s refund policy, last week’s incident report or the contract you signed on Tuesday. It also has a habit of answering confident5AAblog.zyvop.com
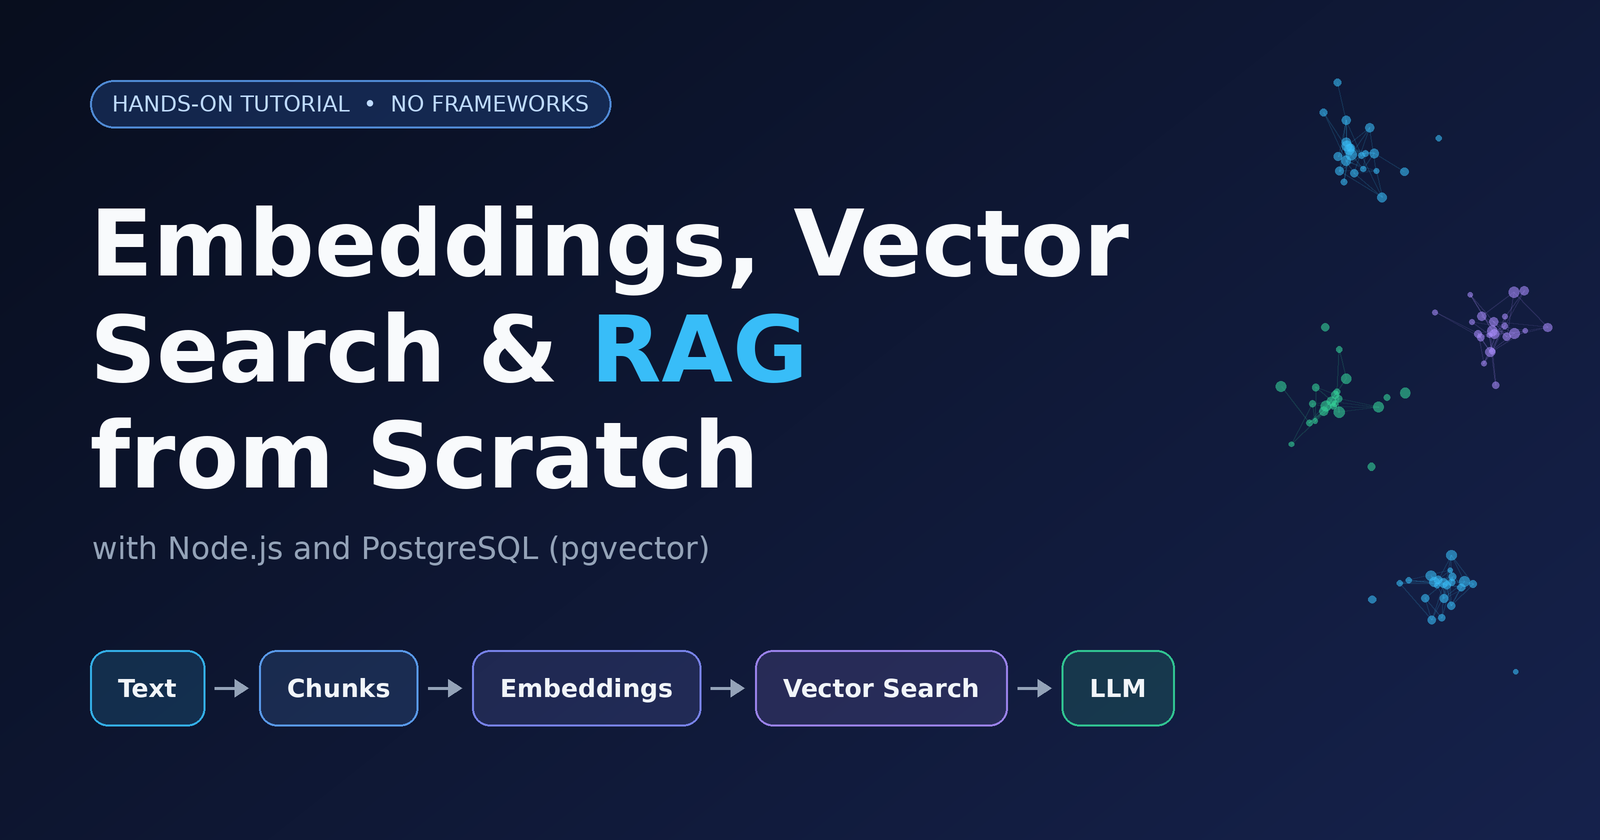
AAsfaq LeeonOct 9 · 13 min readEmbeddings, Vector Search & RAG from Scratch with Node.js and PostgreSQL (pgvector)Once I thought RAG should start with npm install langchain and that time I don't understand the chaining abstractions. One of my friend told me that if something breaks (and it will), you can't debug 3Aleeonscoding.hashnode.dev