Teaching a Small Language Model to Triage Incidents: A Beginner’s Unsloth and QLoRA Tutorial
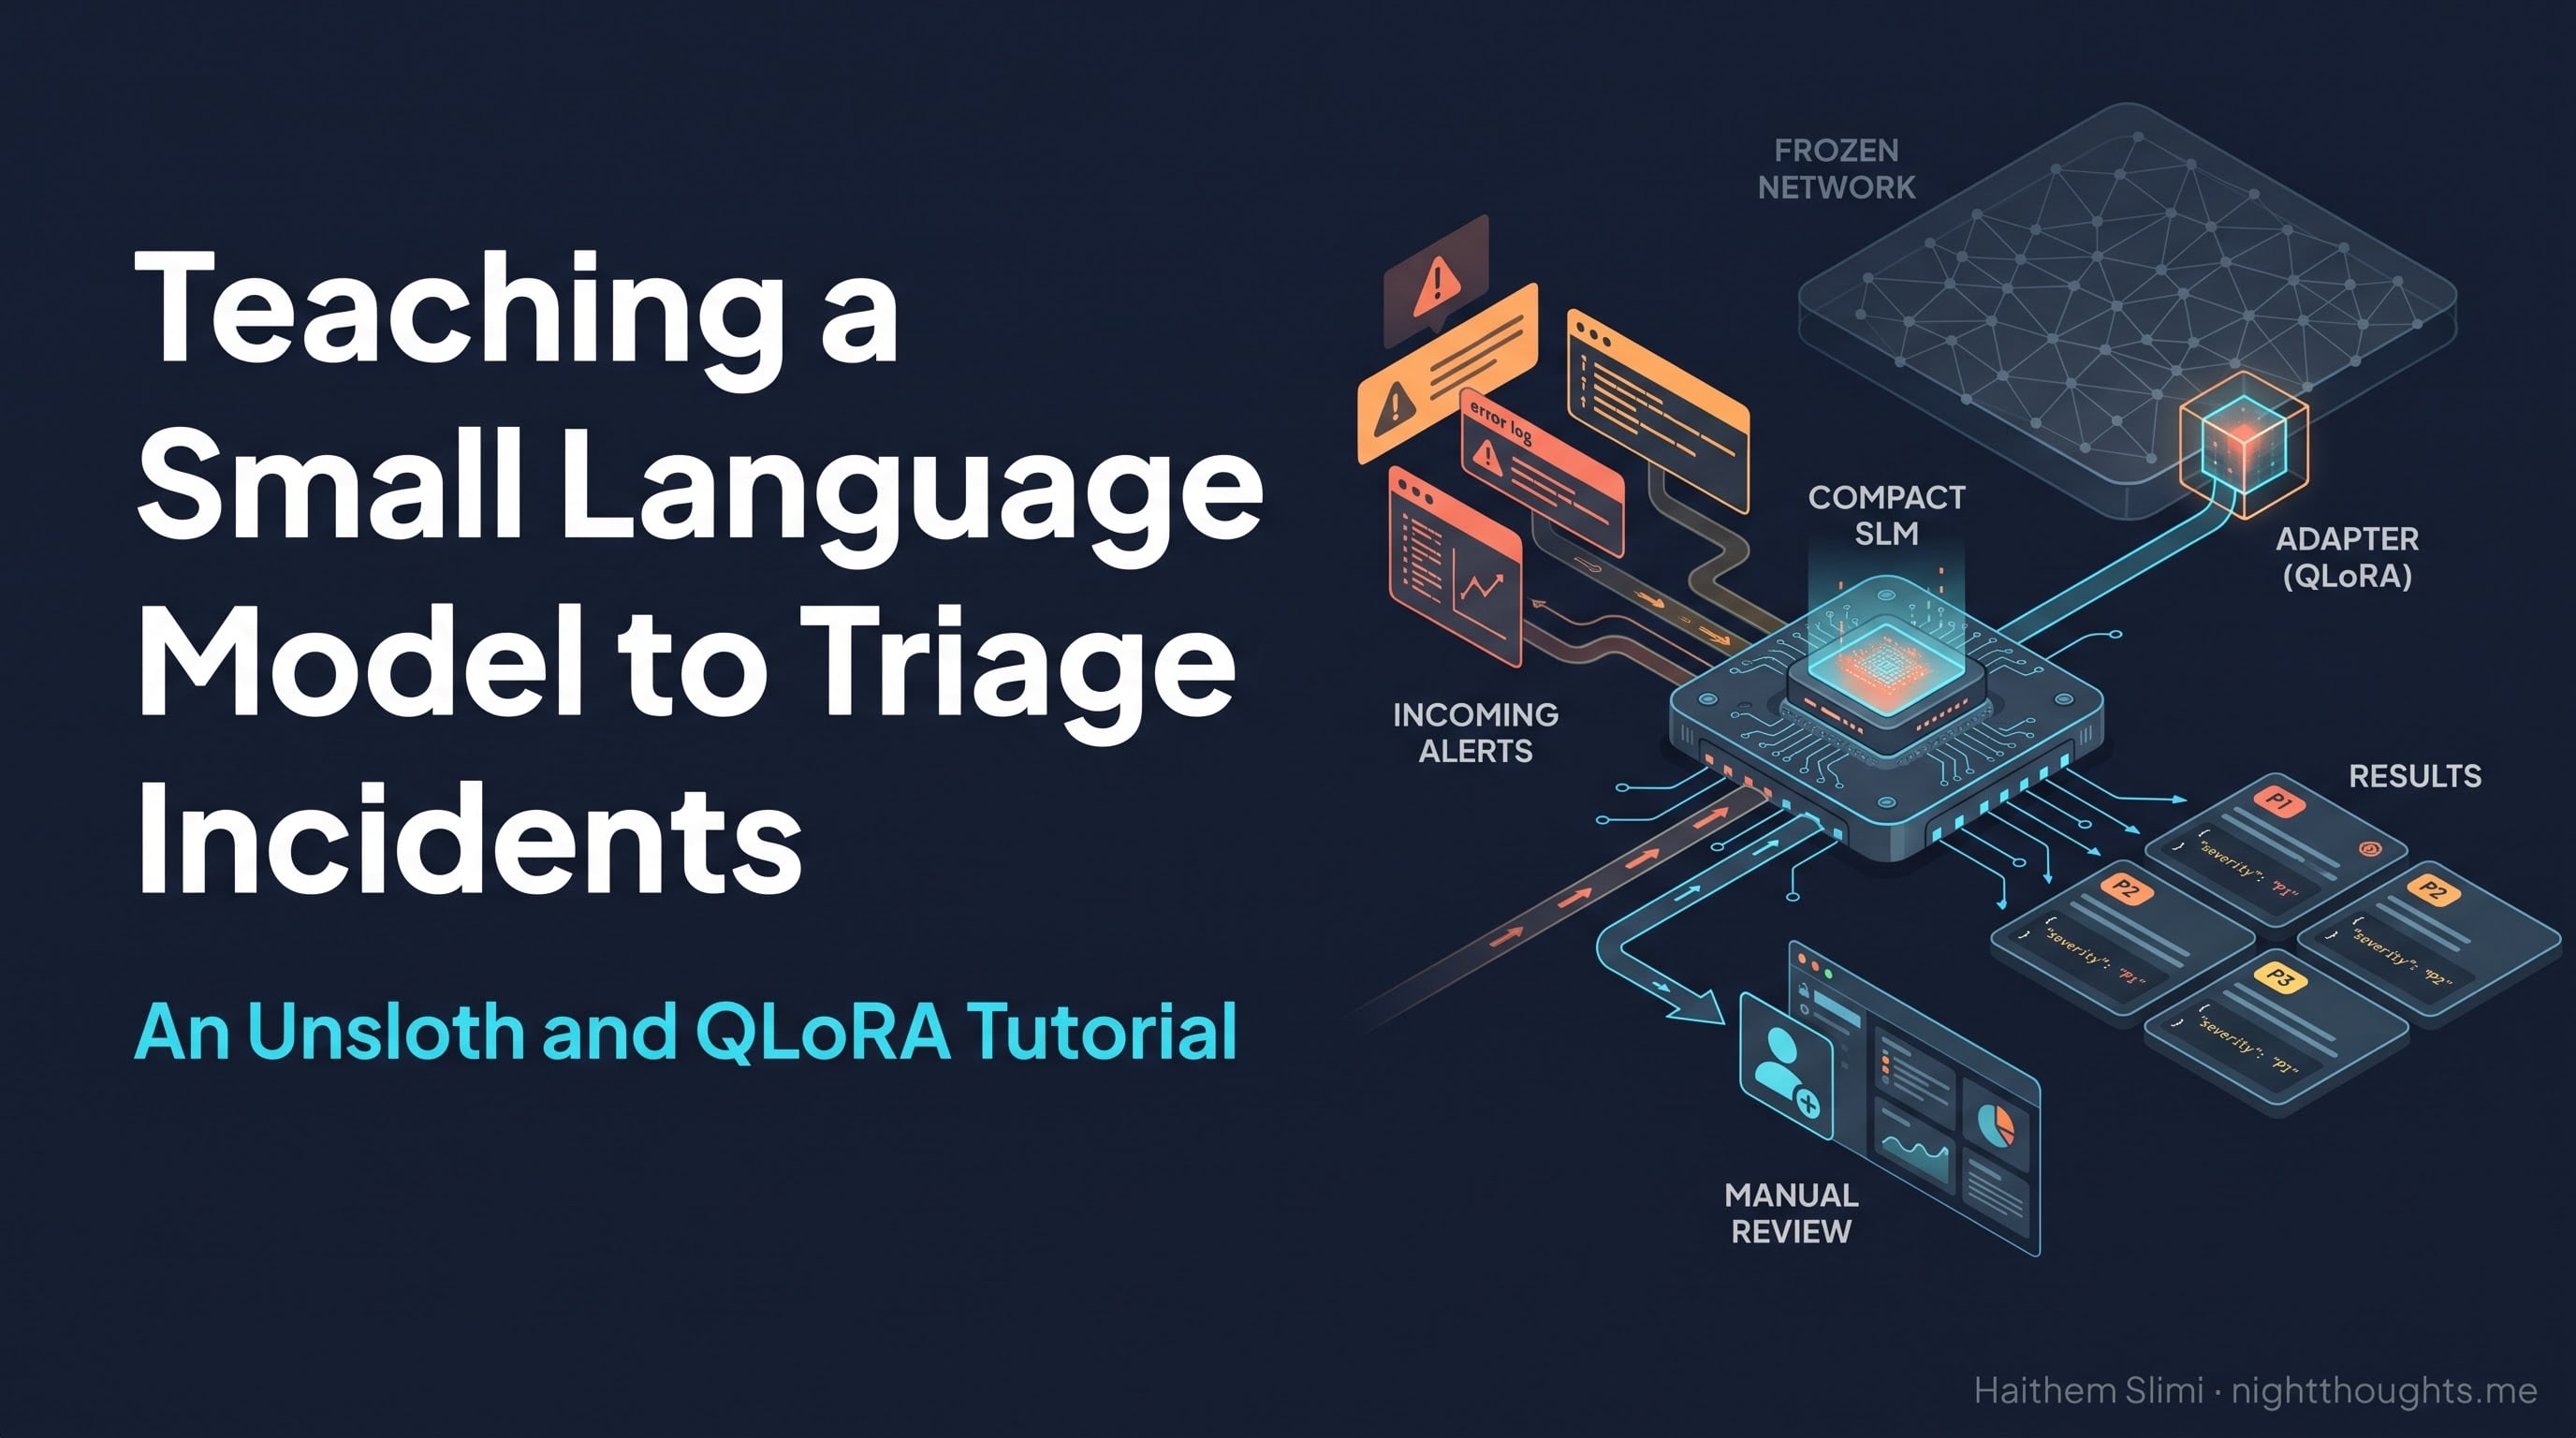
Most fine-tuning tutorials stop when the training loss decreases. I wanted to answer a more useful operational question: can a small language model learn to turn an unstructured incident alert into a
Responses
Markdown supported · ⌘↵ to post
Kartik N V J K
AI Developer | Making AI reliable, trustworthy & accessible to everyone | Active community contributor
Summary accuracy at 0.00% means exact match could never rise above 0.00%, so that row mostly measures the summary. I'd compute exact match over the five structured fields and score the summary on its own. The unknown_worker_saturation case would then count as a full match.