HHaithem Slimi1d ago · 30 min readTeaching a Small Language Model to Triage Incidents: A Beginner’s Unsloth and QLoRA TutorialMost fine-tuning tutorials stop when the training loss decreases. I wanted to answer a more useful operational question: can a small language model learn to turn an unstructured incident alert into a 24KNnightthoughts.me
HHaithem Slimi5d ago · 30 min readTeaching a Small Local Model to Think in DifferentialsMost fine-tuning tutorials end when training loss decreases. I wanted to answer a more interesting question: given a synthetic patient’s symptoms, can a small local model learn not only what is most lnightthoughts.me
RRebiha.comOct 20 · 6 min readLLM Fine-Tuning Services: How to Choose the Right Provider in 2026Choosing an LLM fine-tuning service isn't simply a matter of comparing GPU availability, training speed, or price. The more important question is whether a provider can produce a model that is measurarebiha.hashnode.dev
TTaha husseinOct 20 · 5 min readFine-Tuning vs LoRA vs QLoRA: Understanding Efficient LLM AdaptationModern large language models are powerful, but using a pretrained model does not guarantee that it will perform well on your specific task. You may need a model that follows a particular output formattahahussein.hashnode.dev
MMuhammad Ariel ShakaramiroSep 25 · 7 min readFine-Tuning Llama 3.1 8B for Free on Colab: QLoRA, Unsloth, and a Compression Claim That Doesn't Hold UpAn 8-billion-parameter model usually needs tens of gigabytes of VRAM just to load, let alone retrain. But with 4-bit quantization and LoRA combined, fine-tuning a model that size can run on Colab's frshaka-ai.hashnode.dev
RRahul Sai Indeevar VSep 16 · 10 min readParameter-Efficient Fine-Tuning: From LoRA to QLoRAFine-tuning Large Language Models (LLMs) used to be an option only for organizations with massive compute budgets. Full fine-tuning requires updating and storing every parameter, gradient, and optimiz2rahul-ai.hashnode.dev
PParthaSep 15 · 12 min readLoRA, QLoRA, or Distillation? A No-Nonsense Guide to ChoosingIf you've ever tried to fine-tune a large language model on normal hardware, you know the wall you hit fast. A 7-billion-parameter model trained the old-fashioned way can eat 100+ GB of GPU memory. Morpsarathy.hashnode.dev
DDarsh ShahAug 6 · 16 min readHow to Customize an LLM for AI Agents using SFT and QLoRAIn this tutorial, I’ll show you how to fine-tune a large language model for use in AI agents using supervised fine-tuning with QLoRA. This lets us customize a pre-trained model so it behaves the way w1freecodecamp.org
HHarsh AgaleMay 22 · 5 min readHow I Fine-Tuned Llama 2 Using QLoRA on Free GPU ResourcesTraining and fine-tuning Large Language Models (LLMs) is often considered expensive and hardware-intensive. Most tutorials online assume access to powerful GPUs with large amounts of VRAM, which can bharshagale.hashnode.dev
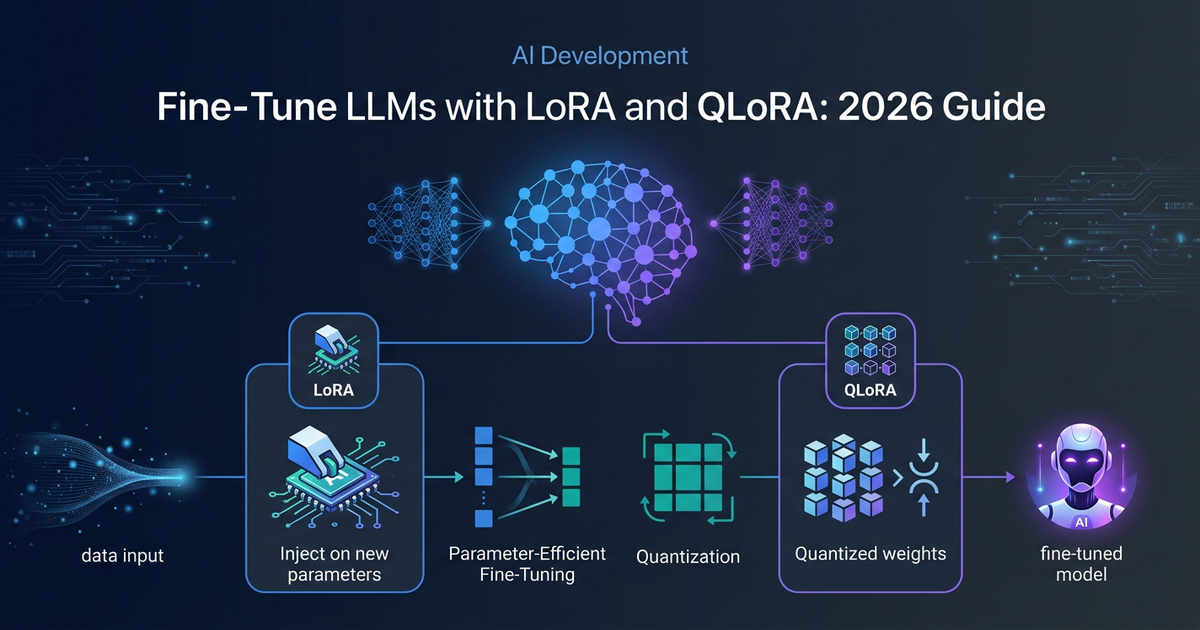
JJangwook KimApr 17 · 12 min readFine-Tune LLMs with LoRA and QLoRA: 2026 GuideTwo years ago, fine-tuning a large language model required a rack of A100s, a machine learning team, and a five-figure cloud bill. In 2026, a single RTX 4070 Ti is enough to specialize a 7B model on your domain data — in an afternoon. That shift happ...1Aeffloow.hashnode.dev